9 Populations & Samples
Stephanie D'Costa and Makenzie O'Neil
Learning Objectives
By the end of this chapter, you will be able to
- Describe the difference between a sample and a population.
- Identify basic sampling methods.
- Describe how intentionality in sampling can lead to more equitable research.
We are usually interested in understanding a specific group of people. This group is known as the population of interest, or simply the population. The population is the collection of all people who have some characteristic in common; it can be as broad as “all people” if we have a very general research question about human psychology, or it can be extremely narrow, such as “all freshmen psychology majors at Midwestern public universities” if we have a specific group in mind.
Samples
In statistics, we often rely on a sample—that is, a small subset of a larger set of data—to draw inferences about the larger set. The larger set is known as the population from which the sample is drawn.
Example #1
You have been hired by the National Election Commission to examine how the American people feel about the fairness of the voting procedures in the U.S.
Whom will you ask?
It is not practical to ask every single American how he or she feels about the fairness of the voting procedures. Instead, we query a relatively small number of Americans and draw inferences about the entire country from their responses. The Americans actually queried constitute our sample of the larger population of all Americans.
A sample is typically a small subset of the population. In the case of voting attitudes, we would sample a few thousand Americans drawn from the hundreds of millions that make up the country. In choosing a sample, it is therefore crucial that it not over-represent one kind of citizen at the expense of others. For example, something would be wrong with our sample if it happened to be made up entirely of Florida residents. If the sample held only Floridians, it could not be used to infer the attitudes of other Americans. The same problem would arise if the sample were comprised only of Republicans. Inferences from statistics are based on the assumption that sampling is representative of the population. If the sample is not representative, then the possibility of sampling bias occurs. Sampling bias means that our conclusions apply only to our sample and are not generalizable to the full population.
Sampling bias is an important consideration for researchers who seek to engage in social justice aligned research practices. Historically, many research samples comprised of white men but the findings from these studies were applied to individuals across racial groups. One key example was the creation of the body mass index (BMI) and its connection to health access. The original research to develop BMI was done in Europe with white men and women. Further research was done in the US in the 1970s but the sample size was still not racial diverse. [1] Nevertheless, the findings were implemented across many racial and ethnic groups, globally. The implications of BMI have led to difficulties with health and insurance access for many racially marginalized communities. It highlights the importance of considering our sampling procedures to ensure that the generalizability of the findings are accurate.
Example #2
We are interested in examining how many math classes have been taken, on average, by current graduating seniors at American colleges and universities during their four years in school.
Whereas our population in example one included all U.S. citizens, now it involves just the graduating seniors throughout the country. This is still a large set since there are thousands of colleges and universities, each enrolling many students. (New York University, for example, enrolls 48,000 students.) It would be prohibitively costly to examine the transcript of every college senior. We therefore take a sample of college seniors and then make inferences to the entire population based on what we find. To make the sample, we might first choose some public and private colleges and universities across the United States. Then we might sample 50 students from each of these institutions. Suppose that the average number of math classes taken by the people in our sample was 3.2. We might speculate that 3.2 approximates the number we would find if we had the resources to examine every senior in the entire population. But we must be careful about the possibility that our sample is non-representative of the population. Perhaps we chose an overabundance of math majors, or chose too many technical institutions that have heavy math requirements. Such bad sampling makes our sample unrepresentative of the population of all seniors.
To solidify your understanding of sampling bias, consider the following examples. Try to identify the population and the sample, and then reflect on whether the sample is likely to yield the information desired.
Example #3
A substitute teacher wants to know how students in the class did on their last test. The teacher asks the ten students sitting in the front row to state their latest test scores. He concludes from their report that the class did extremely well.
What is the sample? What is the population? Can you identify any problems with choosing the sample in the way that the teacher did?
In Example #3, the population consists of all students in the class. The sample is made up of just the ten students sitting in the front row. The sample is not likely to be representative of the population. Those who sit in the front row tend to be more interested in the class and tend to perform higher on tests. Hence, the sample may perform at a higher level than the population.
Example #4
In Example #4, the population is the class of all freshmen at the coach’s university. The sample is composed of 8 volunteers. The sample is poorly chosen because volunteers are more likely to be able to do cartwheels than the average freshman; people who can’t do cartwheels probably did not volunteer! In the example, we are also not told of the gender of the volunteers. Were they all women, for example? That might affect the outcome, contributing to the non-representative nature of the sample (if the school is co-ed).
Sampling Techniques
Next, we need to ask how the sample was selected. The first question to ask about a sample is whether it was chosen at random. Moore, Notz & Fligner (2013)[4] provide two reasons to choose random sampling. The first reason is to eliminate bias in selecting samples from the list of available individuals. The second reason to use random sampling is that the laws of probability allow trustworthy inference about the population.
If every population member is given an equal chance of sample selection, a random sampling method is used. This is known as probability sampling. Otherwise, a nonrandom or sampling with non-probability is employed.
Probability Sampling
Probability Sampling occurs when the researcher can specify the probability that each member of the population will be selected for the sample. It gives the likelihood of the sample being representative of the population, and is the preferred sampling technique for conducting research, although it can be more difficult to do. There are several types of probability sampling techniques
Simple Random Sampling
Simple Random Sampling (SRS): a reliable method of obtaining information where every single member of a population is chosen randomly, merely by chance. Each person has the same probability of being chosen to be a part of a sample. An SRS of size n individuals from the population is chosen in such a way that every set of n individuals has an equal chance to be the sample actually selected. A specific advantage of simple random sampling is that it is the most straightforward method of probability sampling. A disadvantage is that you may not find enough individuals with your characteristic of interest, especially if that characteristic is uncommon.
Sometimes it is not feasible to build a sample using simple random sampling. To see the problem, consider the fact that both Dallas and Houston competed to be hosts of the 2012 Olympics. Imagine that you had been hired to assess whether most Texans preferred Houston to Dallas as the host, or the reverse. Given the impracticality of obtaining the opinion of every single Texan, you had to construct a sample of the Texas population. But notice how difficult it would have been to proceed by simple random sampling. For example, how would you have contacted those individuals who didn’t vote and didn’t have a phone? Even among people you found in the telephone book, how could you have identified those who had just relocated to another state (and had no reason to inform you of their move)? What would you have done about the fact that, since the beginning of the study, an additional 4,212 people took up residence in the state of Texas? As you can see, it is sometimes very difficult to develop a truly random procedure. For this reason, other kinds of sampling techniques have been devised. We now discuss two of them.
Stratified Sampling
Since simple random sampling often does not ensure a representative sample, a sampling method called stratified random sampling is sometimes used to make the sample more representative of the population. This method can be used if the population has a number of distinct “strata” or groups. In stratified sampling, you first identify members of your sample who belong to each group. Then you randomly sample from each of those subgroups in such a way that the sizes of the subgroups in the sample are proportional to their sizes in the population.
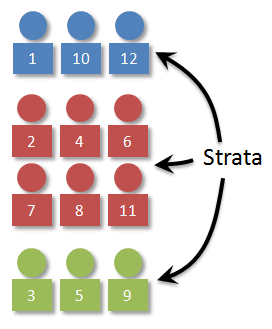 Let’s take an example: Suppose you were interested in views on capital punishment at an urban university. You have the time and resources to interview 200 students. The student body is diverse with respect to age; many older people work during the day and enroll in night courses (average age is 39), while younger students generally enroll in day classes (average age of 19). It is possible that night students have different views about capital punishment than day students. If 70% of the students were day students, it makes sense to ensure that 70% of the sample consisted of day students. Thus, your sample of 200 students would consist of 140 day students and 60 night students. The proportion of day students in the sample and in the population (the entire university) would be the same. Inferences to the entire population of students at the university would therefore be more secure.
Cluster Sampling
Cluster Sampling: a method where statisticians divide the entire population into clusters or sections representing a population. Demographic characteristics, such as race/ethnicity, gender, age, and zip code can be used to identify a cluster. Cluster sampling can be more efficient than simple random sampling, especially where a study takes place over a wide geographic region.
An extended version of cluster sampling is multi-stage sampling, where, in the first stage, the population is divided into clusters, and clusters are selected. At each subsequent stage, the selected clusters are further divided into smaller clusters. The process is completed until you get to the last step, where some members of each cluster are selected for the sample. Multi-stage sampling involves a combination of cluster and stratified sampling.
The U.S. Census Bureau uses multistage sampling by first taking a simple random sample of counties in each state, then taking another simple random sample of households in each county, and collecting data on those households.
Sample Size Matters
Recall that the definition of a random sample is a sample in which every member of the population has an equal chance of being selected. This means that the sampling procedure, rather than the results of the procedure, defines what it means for a sample to be random. Random samples, especially if the sample size is small, are not necessarily representative of the entire population. For example, if a random sample of 20 subjects were taken from a population with an equal number of males and females, there would be a nontrivial probability (.06) that 70% or more of the sample would be female. Such a sample would not be representative, although it would be drawn randomly. Only a large sample size makes it likely that our sample is close to representative of the population. For this reason, inferential statistics take into account the sample size when generalizing results from samples to populations. In later chapters, you’ll see what kinds of mathematical techniques ensure this sensitivity to sample size.
Non-Probability Sampling
Alternatively, Non-probability sampling occurs when the researcher cannot specify the probability that each member of the population will be selected for the sample. Non-probability sampling cannot assure the representativeness of a sample as well as probability sampling. However, it tends to be simpler and cheaper for researchers to conduct, and thus psychological research more often involves non-probability sampling techniques.
Some examples of common forms non-probability sampling include: Convenience sampling (studying individuals who happen to be nearby and willing to participate); Snowball sampling (in which existing research participants help recruit additional participants for the study), and self-selection sampling (in which individuals choose to take part in the research on their own accord, without being approached by the researcher directly).
Equity Activity: Applying an equity lens to sampling
The National Survey of American Life (NSAL) is the most comprehensive and detailed study of mental disorders and the mental health of Americans of African descent. The study was conducted by the Program for Research on Black Americans (PRBA) within the Institute for Social Research at the University of Michigan.[2] According to Jackson et al. (2004), the study includes “a large, nationally representative sample of African Americans, permitting an examination of the heterogeneity of experience across groups within this segment of the Black American population. Most prior research on Black Americans mental health has lacked adequate sample sizes to systematically address this within-race variation.
Special emphasis of the study is given to the nature of race and ethnicity within the Black population by selecting and interviewing national samples of African American (N=3,570) and Afro-Caribbean (N=1,623) immigrants, and second and older generation populations. National multi-stage probability methods were used in generating the samples. This means that the researcher divided the Americans of African descent into groups (clusters) and then randomly sampled within those clusters. For generalizability, probability sampling methods were used in the study for stronger statistical inferences.
License & Attribution
“Populations & Samples” by Stephanie D’Costa and Makenzie O’Neil is adapted from “Inferential Statistics” by Mikki Hebl and David Lane; “Inferential Statistics: Sampling Methods” by Yvonne Anthony under a CC BY-NC-SA 4.0 license; and Conducting Surveys by Rajiv Jhangiani, I-Chant A. Chiang, Carrie Cuttler, & Dana C. Leighton under a CC BY-NC-SA 4.0 license.
“Populations & Samples” is licensed under CC BY-NC-SA 4.0.
- Pray, R., Riskin, S., & Riskin, S. I. (2023). The history and faults of the body mass index and where to look next: a literature review. Cureus, 15(11). ↵
- Jackson JS, Torres M, Caldwell CH, Neighbors HW, Nesse RM, Taylor RJ, Trierweiler SJ, & Williams DR (2004). The National Survey of American Life: A Study of Racial, Ethnic and Cultural Influences on Mental Disorders and Mental Health. International Journal of Methods in Psychiatric Research, Volume 13, Number 4 ↵
